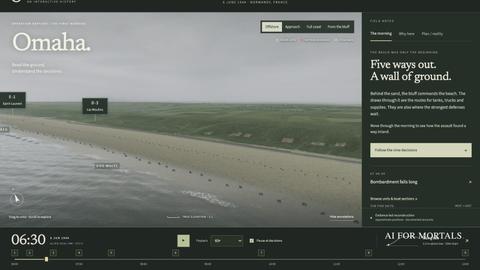
The prompt
Prompt coming.
The exact prompt from the published test.
The builds
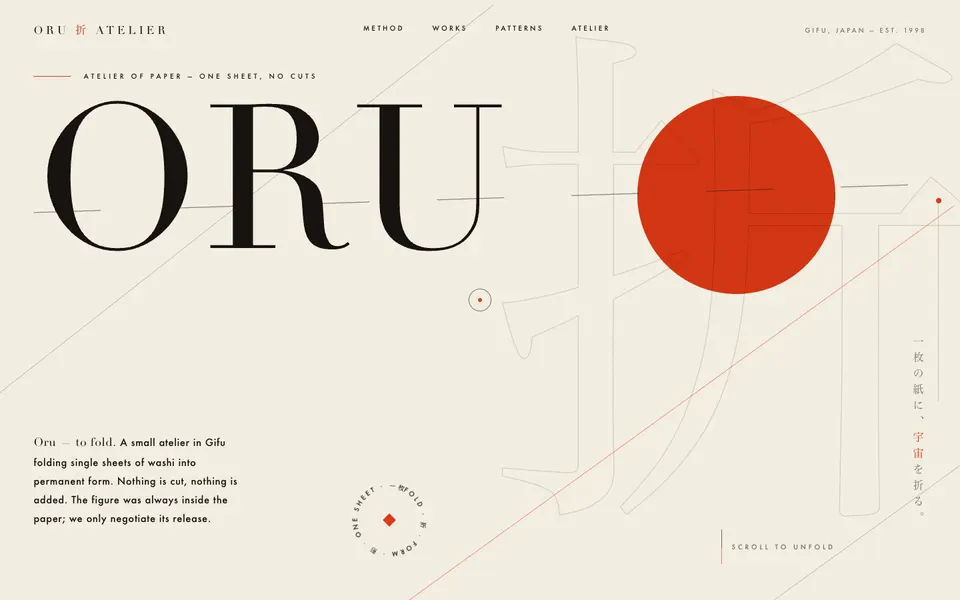
Kimi K3 · Screenshot of the buildRuns in your browser
Featured in
Kimi K3 vs Fable 5 vs. GPT 5.6 (Raw Results)
This build’s chapter starts at 36:25.
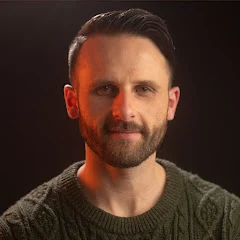
Each model designs an original, award-worthy website, judged on pure taste.
Prompt coming.
The exact prompt from the published test.
Kimi K3 · Screenshot of the buildRuns in your browser
Featured in
This build’s chapter starts at 36:25.

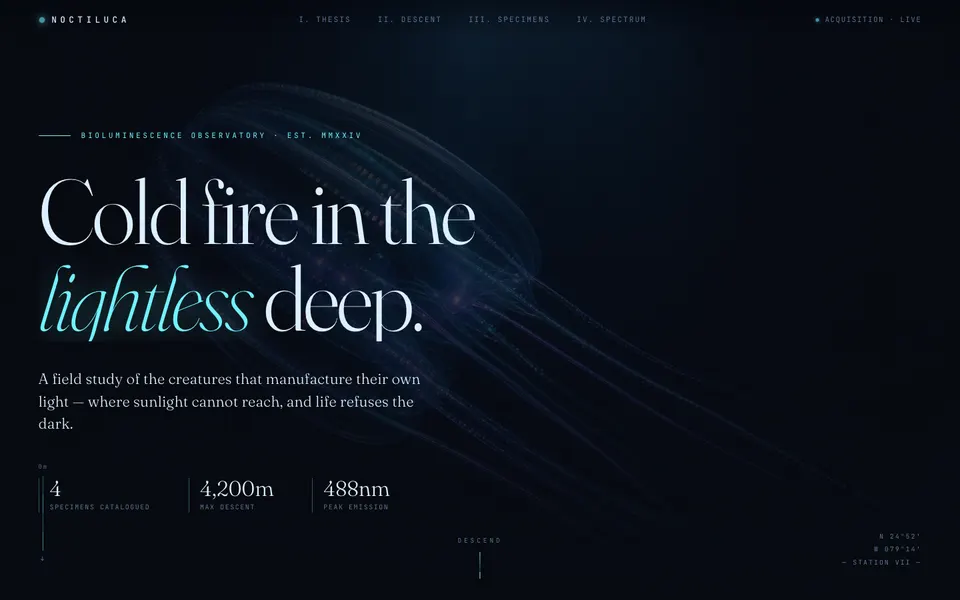
Then a design showcase site, total creative freedom, meant to show off peak taste. Both models, given a blank canvas, independently reached for the deep ocean. GLM made NOCTILUCA, a bioluminescence field study; Kimi made ABYSSAL, a vertical survey of the deep. Here is the prompt:

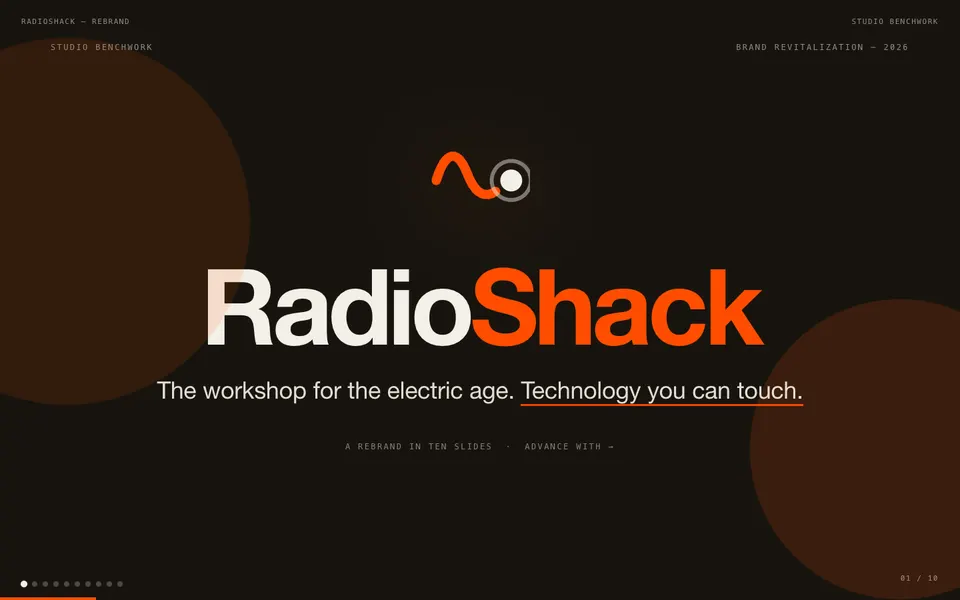
A full RadioShack rebrand delivered as a PowerPoint deck with GPT Image Gen.

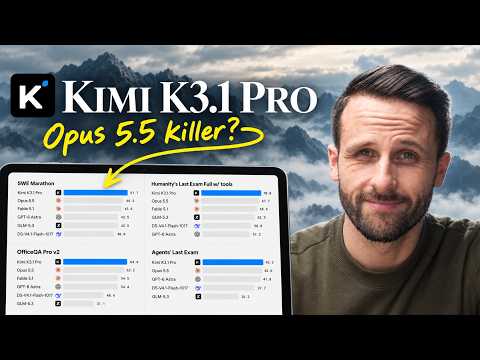
I tested Moonshot's open-weight model against Opus 5.5, Fable 5.1, GPT-6 Astra and DeepSeek V4.1 Flash.

Opus 5.5 came first in 16 of the 21 apps, games, websites and videos Pat Simmons had AI models build from identical prompts, 18 of them judged blind. Every build's ranking and cost, and which model to use for which job.

Seven builds in two rounds: Astra against Fable 5.1 on three, then GPT-5.6 Sol added on four more. Every prompt, every build, and what each one cost.

Pat Simmons gave AI models the same builds, three to five at a time, and logged every run's cost, tokens and minutes. DeepSeek V4.1 Flash cost as little as $1.00 a build and Fable 5.1 as much as $592.37, and the two cheapest models placed low in the blind rankings. The page also lists every model's API price and the main plans, checked November 10, 2026.
AI FOR MORTALS.
Every weekday, the practical AI updates that matter, and exactly what to do with them.
The latest in AI, in plain English. Free, every weekday.